
Imagine running a corporate learning platform with thousands of employees completing courses, watching training videos, taking assessments, and earning certifications every day.
Your LMS captures all these activities, but when executives request a company-wide skills report, the numbers don’t match across departments.
The HR dashboard shows one completion rate, the LMS reports another, and the compliance team has an entirely different spreadsheet.
Frustrating, right?
This is where learning data pipelines for enterprise analytics and reporting become incredibly valuable.
Modern organizations generate enormous amounts of training information, but collecting data isn’t the same as making it useful. Without reliable processing and integration, even the most advanced learning platform can struggle to deliver trustworthy insights.
A well-designed data pipeline connects information from multiple learning systems, cleans inconsistent records, organizes datasets, and delivers actionable results to reporting tools.
It helps organizations understand training participation, competency development, learning effectiveness, and workforce readiness.
More importantly, it creates a dependable foundation for evidence-based decisions.
Let’s explore how enterprise learning data pipelines work, which technologies support them, and how organizations can turn scattered learning records into meaningful business intelligence.
1. Understanding Learning Data Pipelines in Enterprise LMS Environments
A learning data pipeline is a series of processes that moves information from its original source into systems designed for analysis and reporting.
Think of it as the infrastructure connecting everyday learning activities with the dashboards used by managers, HR professionals, and business leaders.
Without this connection, valuable training information often remains isolated inside individual platforms.
Why Enterprise Learning Data Becomes Fragmented
Large organizations rarely depend on a single learning application.
They might use an enterprise LMS for mandatory training, a learning experience platform for professional development, external course providers for certifications, and specialized tools for technical assessments.
Human resources systems also contain relevant information about employees, departments, job roles, and reporting structures.
Each application may store information differently.
One system might identify a learner through an employee number, while another uses an email address or platform-specific user ID.
Even basic concepts such as course completion can vary between systems.
A training provider might consider a course completed when all videos have been watched, while another requires a passing assessment score.
Without standardized data definitions, combining these records becomes difficult.
How a Learning Data Pipeline Works
A typical pipeline follows a logical sequence.
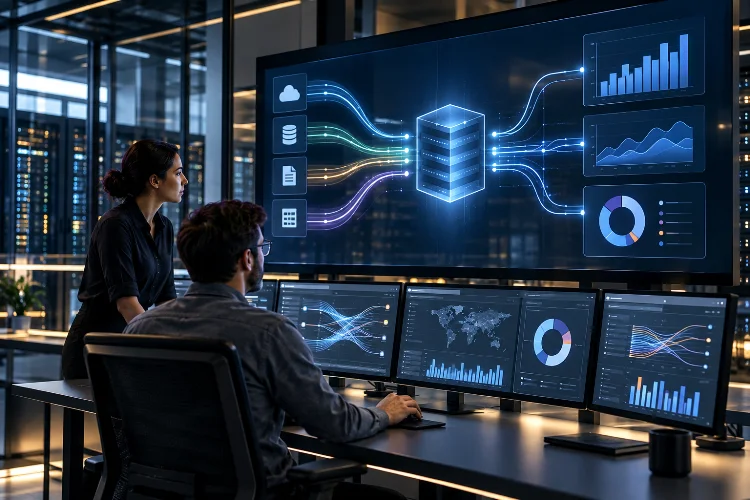
Learning applications generate records, ingestion services collect them, transformation processes standardize the information, and analytical storage systems organize the results.
Finally, business intelligence tools use the processed datasets to produce reports and visualizations.
For example, an employee completes a cybersecurity course.
The LMS generates a completion event, the pipeline validates the record, and the reporting system updates the employee’s training status.
This arrangement reduces manual data consolidation and creates a more reliable reporting process.
2. Collecting Learning Data From Multiple Sources
Before building sophisticated analytics, organizations need a dependable way to collect learning information.
This stage is called data ingestion.
The challenge isn’t simply transferring records between systems. It’s capturing the right information while preserving accuracy, context, and traceability.
Connecting LMS Platforms Through APIs and Database Integration
Application programming interfaces, or APIs, are commonly used to exchange information between learning platforms and analytical systems.
An enterprise might regularly retrieve enrollments, course completions, and assessment results through an LMS API.
Other systems may support database replication, change data capture, webhooks, or scheduled file exports.
Change data capture, often abbreviated as CDC, identifies database changes and makes them available to downstream systems without repeatedly copying entire tables.
This can be useful for large enrollment databases where only a small percentage of records change each day.
However, ingestion methods should reflect the source system’s capabilities.
Direct database access may introduce unnecessary security and operational risks if an official integration interface is already available.
Using xAPI and Caliper for Learning Events
Learning data extends beyond traditional course completion records.
Organizations increasingly want to understand interactions involving simulations, videos, digital assessments, and external learning resources.
The Experience API, or xAPI, provides a standardized method for representing learning activities and exchanging statements between compatible technologies.
These statements commonly identify an actor, an action, and an object.
For example, a statement might describe an employee completing a safety simulation.
The statements can be stored in a Learning Record Store, or LRS, which is designed to support xAPI learning records.
Another relevant standard is 1EdTech Caliper Analytics.
Caliper defines metric profiles and event vocabularies for describing educational activities in a structured, interoperable way.
Both approaches can help organizations improve the consistant interpretation of activity data collected from different applications.
However, using a common standard doesn’t automatically resolve every difference between business rules.
Organizations still need documented definitions for meaningful learning outcomes.
3. Choosing Between Batch and Real-Time Data Processing
Not every learning report needs information that updates immediately.
Some organizations require daily training summaries, while others need rapid visibility into certification status or critical compliance activities.
Selecting the appropriate processing method helps balance performance, cost, and operational complexity.
Batch Processing for Scheduled Reporting
Batch processing collects and transforms information at scheduled intervals.
For example, an organization might refresh its training performance warehouse every night.
During that process, the pipeline retrieves new learning records, validates them, and updates reporting tables.
This approach works well for monthly training reports, departmental participation trends, and historical learning analysis.
It can also be easier to maintain than continuously running streaming infrastructure.
However, users must understand the reporting delay.
If a dashboard updates once every 24 hours, an employee who completed mandatory training ten minutes ago may not immediately appear as compliant.
That isn’t necessarily a system failure.
It’s a consequence of the selected refresh schedule.
Real-Time Streaming for Immediate Insights
Streaming pipelines process events continuously or in small increments as information becomes available.
For example, a company conducting a major compliance training campaign might want rapid visibility into new completions.
Streaming technology can support these requirements by moving learning events through message brokers and processing services.
Apache Kafka is one widely used event-streaming technology.
Its delivery guarantees require careful consideration because at-least-once delivery can result in duplicate messages when retries occur.
A learning analytics pipeline should therefore use event identifiers and idempotent processing to avoid counting the same completion multiple times.
Combining Both Approaches
For many organizations, a hybrid model makes the most sense.
Streaming can support time-sensitive alerts and operational dashboards, while batch processing handles historical aggregation and detailed reporting.
For example, newly completed certifications might update a compliance monitoring view quickly.
Meanwhile, a scheduled process could generate a comprehensive monthly workforce development report.
The key is choosing processing frequency based on business value rather than assuming everything must happen in real time.
4. Designing Reliable ETL and ELT Workflows
Once learning data enters the pipeline, it must be transformed into information that analysts and reporting systems can use.
Two common approaches are Extract, Transform, Load (ETL) and Extract, Load, Transform (ELT).
Although the names sound similar, the processing sequence is different.
Understanding ETL and ELT
ETL transforms information before loading it into the destination analytical system.
For example, an integration process could extract assessment results, remove invalid records, standardize timestamps, and then load the cleaned data into a reporting database.
ELT loads source information into analytical storage before applying transformations.
This approach can be useful when organizations want to preserve original records and process them using a cloud warehouse or lakehouse.
Neither strategy is automatically superior.
The right choice depends on data volumes, processing requirements, infrastructure capabilities, and governance considerations.
Using the Medallion Architecture
A practical approach for larger analytical environments is the medallion architecture.
It organizes information into three progressive layers: Bronze, Silver, and Gold.
Microsoft’s modern data warehouse guidance describes these layers as raw ingestion, cleansed and standardized information, and business-ready analytical datasets.
For an enterprise LMS, the Bronze layer could preserve incoming activity records with source metadata.
The Silver layer could standardize learner identifiers, validate timestamps, remove duplicate events, and reconcile information from different platforms.
The Gold layer could contain reporting datasets such as monthly completion rates, department-level competency summaries, and certification compliance indicators.
This structure makes transformations easier to audit and allows teams to reprocess information when business rules change.
Handling Duplicate and Late-Arriving Events
Real-world learning data is rarely perfectly organized.
An LMS may resend a completion event, an external provider might deliver records several hours late, or a previously completed course could be corrected.
Pipelines must account for these situations.
Stable event identifiers help distinguish repeated deliveries from genuine new activity.
Event timestamps should also be separated from ingestion timestamps so analysts can understand when learning happened and when the system received the information.
For historical reports, late-arriving events may require previously calculated summaries to be updated.
This is especially important when compliance or financial reporting depends on accurate reporting periods.
5. Building Analytics-Ready Learning Data Models
Collecting and cleaning information is only part of the job.
The next challenge involves organizing learning records so that reporting tools can retrieve meaningful results efficiently.
This requires designing data models around business questions rather than simply duplicating operational LMS tables.
Creating Fact and Dimension Tables
A common analytical approach is dimensional modeling.
Fact tables store measurable activities, while dimension tables describe the entities associated with those activities.
For example, a learning activity fact table might store assessment attempts, enrollment events, or verified completions.
Related dimensions could describe learners, courses, departments, dates, job roles, and organizational units.
This structure allows reporting applications to calculate performance across different perspectives.
A manager could review course completions by department, while an HR analyst examines training participation across job families.
However, fact tables require carefully defined granularity.
A table containing one row per assessment attempt shouldn’t be treated as if it contains one row per learner.
Confusing these levels can produce inflated counts and misleading metrics.
Defining Reliable Learning KPIs
Organizations should agree on metric definitions before creating dashboards.
Consider the term “course completion rate.”
Does it represent completed enrollments divided by all enrollments, or the percentage of unique learners who completed a required program?
Both calculations may be useful, but they answer different questions.
A clear metric definition should identify the numerator, denominator, reporting period, eligible population, and applicable filters.
For example, a compliance completion rate might measure employees who completed required training divided by employees currently required to complete it.
This is different from the completion rate for a voluntary course.
A shared semantic layer can make these definitions available across reporting applications.
The objective is to ensure that executives, managers, and learning administrators interpret the same metric in the same way.
Preserving Historical Context
Enterprise structures change over time.
Employees transfer departments, courses receive updates, and certification requirements evolve.
If reports use only current organizational information, historical results may become misleading.
For example, an employee who transferred from Sales to Operations in October shouldn’t automatically have all previous training attributed to Operations.
Historical snapshots or slowly changing dimensions can preserve the relevant relationships at the time an activity occurred.
Course and assessment version identifiers are equally useful.
These details support accurate historical comparisons and reduce confusion when organizations revise learning requirements.
6. Maintaining Data Quality, Security, and Pipeline Reliability
An impressive analytics dashboard is worth very little if the underlying information can’t be trusted.
Enterprise learning data pipelines need ongoing validation, secure access controls, and dependable recovery procedures.
These capabilities should be built into the processing workflow instead of being added after reporting problems appear.
Automating Data Quality Checks
Data validation helps identify incomplete, duplicated, or inconsistent records before they reach business reports.
For example, an enrollment record should have a valid learner identifier and course reference.
A completion timestamp shouldn’t be missing when a record is marked as completed, unless the underlying business model explicitly allows that situation.
The dbt framework supports common data tests such as uniqueness, non-null values, accepted values, and relationships between datasets.
These checks can run automatically as part of transformation workflows.
However, technical validation alone isn’t enough.
A dataset can pass database tests while still using an incorrect business definition.
Learning and HR teams should therefore participate in reviewing important reporting rules.
Orchestrating Reliable Pipeline Workflows
Data pipelines usually contain dependent tasks.
An organization might need to ingest enrollment information before calculating completion statistics.
Workflow orchestration tools help coordinate these activities.
Apache Airflow uses directed acyclic graphs, or DAGs, to define tasks, schedules, and execution dependencies.
For example, one workflow could extract new records, validate them, update reporting models, and publish refreshed dashboard datasets.
If an upstream task fails, dependent tasks can be prevented from using incomplete results.
Teams should also configure retries, alerting, and appropriate recovery procedures.
Pipeline monitoring should include data freshness, record volumes, processing delays, validation failures, and unsuccessful jobs.
Protecting Learner Privacy
Learning records may contain employee identities, assessment results, certification histories, and other potentially sensitive information.
Access should be limited according to legitimate reporting responsibilities.
Managers may need department-level completion statistics without receiving unrestricted access to individual assessment details.
Role-based authorization, encryption, pseudonymization, and retention policies can help reduce unnecessary exposure.
The NIST Privacy Framework offers guidance for identifying and managing privacy risks within organizational data processing activities.
Multi-tenant learning environments also require safeguards that prevent information from one customer or organization appearing in another customer’s reports.
Reliable analytics should never come at the expense of learner privacy.
7. Turning Learning Data Into Actionable Enterprise Reporting
The final stage of the pipeline is where technical processing becomes useful to the business.
Dashboards and reports translate structured information into insights that managers can understand and act upon.
However, successful enterprise analytics requires more than displaying attractive charts.
Building Role-Specific Learning Dashboards
Different stakeholders need different perspectives.
Executives may want high-level workforce capability trends, compliance exposure, and progress toward strategic development goals.
Learning administrators often need detailed visibility into enrollments, overdue courses, certification expirations, and assessment performance.
Department managers may focus on team-specific training requirements.
Instead of giving everyone the same dashboard, organizations can create reporting views aligned with individual responsibilities.
A single governed dataset can support these experiences while maintaining shared metric definitions.
For example, imagine a company with 80,000 employees generating eight trackable learning events per person each day.
That would produce approximately 640,000 events daily, or 19.2 million events during a 30-day period.
These are illustrative figures, but they demonstrate why efficient data aggregation and analytical storage matter.
Connecting Learning Results With Business Outcomes
Training participation is useful to measure, but organizations increasingly want to understand whether learning improves workplace performance.
An enterprise analytics environment can combine training records with approved operational indicators.
For instance, customer service training might be analyzed alongside resolution accuracy and customer satisfaction.
Cybersecurity training could be compared with relevant security awareness assessments or incident reporting behavior.
However, correlation doesn’t automatically establish causation.
Business outcomes are influenced by staffing, processes, technology, and many other factors.
Where feasible, organizations should use controlled comparisons or well-designed pilot programs to evaluate whether learning interventions contribute to measurable improvements.
Creating a Practical Implementation Roadmap
Building an enterprise learning data pipeline doesn’t require introducing every available technology at once.
A sensible first step is identifying the reporting questions that matter most.
For example, an organization could begin by consolidating mandatory training completions from two learning systems.
The initial pipeline might use scheduled API extraction, straightforward transformations, and a small analytical database.
Once the results become reliable, the team could introduce additional sources, richer competency information, and automated reporting.
Streaming technology and advanced analytics can follow when the business case supports them.
This incremental approach reduces implementation risk and allows teams to address data quality problems early.
Measuring Pipeline Success
The pipeline itself needs performance indicators.
Useful measures include data freshness, processing success rates, reconciliation accuracy, reporting latency, infrastructure costs, and the number of manual corrections required.
Business users should also provide feedback about whether reports answer their actual questions.
If analysts still need to combine multiple spreadsheets every month, the pipeline may not be delivering its intended value.
Regular reviews help teams identify new requirements, adjust transformations, and remove unnecessary processing steps.
The long-term goal is a relevent, dependable analytics environment that supports decisions without creating excessive maintainance overhead.
Learning data pipelines are essential for turning fragmented training records into reliable enterprise intelligence.
By connecting LMS platforms, standardizing learning events, and designing efficient ETL or ELT workflows, organizations can create a stronger foundation for reporting and analysis.
Batch processing, streaming technologies, structured analytical models, and automated validation each contribute to a scalable data environment.
Equally important are privacy protections, shared metric definitions, and reporting tools that connect learning activities with meaningful business objectives.
The best architecture isn’t necessarily the most complicated. It’s the one that consistently delivers accurate information when stakeholders need it.
Ready to improve your enterprise learning analytics? Start by auditing your existing data sources, defining critical reporting metrics, and building a small, reliable pipeline around your highest-priority use case.
Better learning decisions begin with better data.